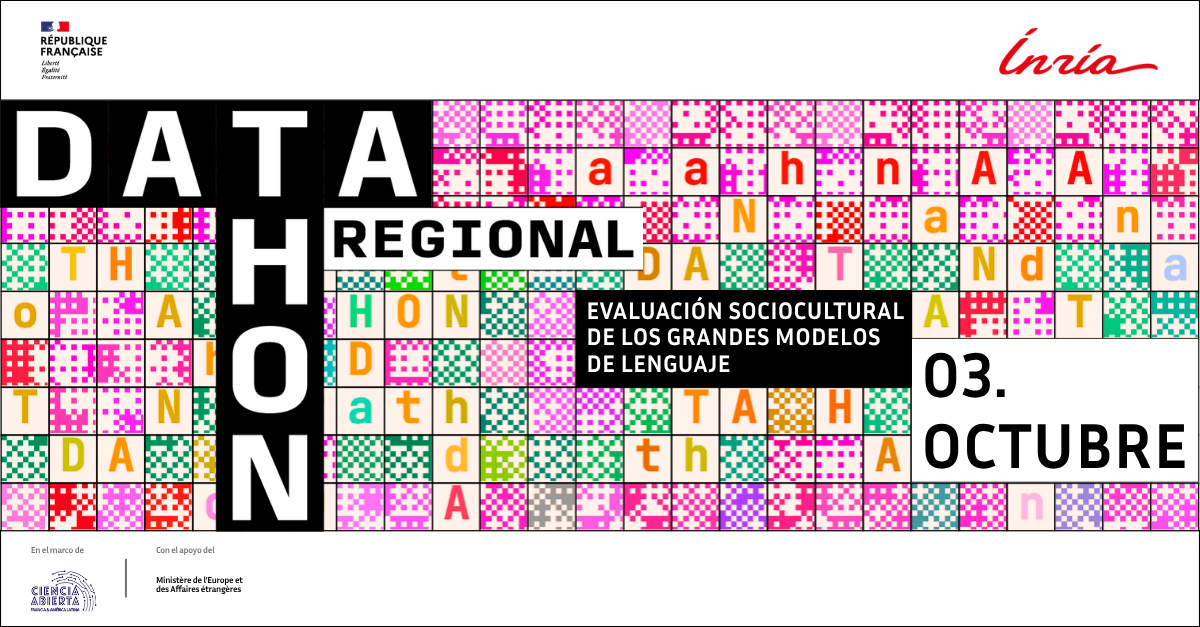
Registration is now open to participate in the Regional Datathon: Sociocultural Evaluation of Large Language Models, organized by Inria Chile on October 3
Date :
Large language models are massively used in Latin America, leading in usage rates (76% of the adult population in Chile uses them, one of the highest rates in the world) and in purchases of generative AI payment applications (Brazil is the third-largest market globally for OpenAI).
However, the data used to train these models primarily comes from countries in the Northern Hemisphere and is in English, which generates biased or knowledge-gap content when applied to cultural contexts of the Global South due to the absence or underrepresentation of data in their training.
The Regional Datathon seeks to correct the cultural coverage asymmetry that leads to social and cultural biases in generative AI through direct contributions from Latin American students who know their cultural context firsthand, and to conduct an in-depth diagnosis of cultural, linguistic, historical, gender, and minority biases in large language models.
The "Regional Datathon: Sociocultural evaluation of large language models" aims to conduct an in-depth diagnosis of the sociocultural coverage asymmetry of generative AI and contribute to its correction.
How? Thanks to contributions from Latin American students who understand their sociocultural context firsthand and who, for one day, will work in multidisciplinary teams to challenge and "trick" large language models (LLMs).
For one day, students from various Latin American countries will gather at their universities to work in diverse teams, creating questions that challenge large language models.
The goal? To create the largest possible dataset of Latin American questions, represent the sociocultural diversity of Latin America, and foster interdisciplinary collaboration among students.
During the day of the Datathon, students will work collaboratively, uploading their multiple-choice questions (MCQs) to a platform created for the event, which will then be evaluated.
Participating student teams must:
→ Create a set of questions following the multiple-choice format (only one correct answer out of four).
→ Provide a list of questions designed to capture specific knowledge of their region, country, or culture, where only one of the proposed options is the correct answer.
For example, a question could be:
The winning team will be the one that best challenges the large language models. The evaluation will be conducted as follows:
After the evaluation: a regional winning team will be selected and announced on the same day during the Regional Datathon and the opening of the France-Latin America Meeting on Open Science.
In some participating countries, a national winning team may also be chosen by the operational advisor, i.e., the French Embassy in their country.
On Saturday, October 3, from 11:00 to 21:00 (UTC-3), the Regional Datathon will be held simultaneously in the participating countries: Argentina, Brazil, Chile, Ecuador, Guatemala, Mexico, Paraguay, Peru, and Uruguay (preliminary list).
The university or academic institution from one of the listed countries must register through the "University Registration" form available in this link.
Once the academic institution is registered, the Student team registration can proceed.
Student teams must register through the "Team Registration" form, available here.
Student teams must consist of:
To register, teams must choose:
To participate, both academic institutions and student participants must accept:
All details, including the mentioned documents and registration links, are available on the dedicated page: datathonregional.inria.cl
The "Regional Datathon: Sociocultural Evaluation of Large Language Models" is organized by Inria Chile, with support from the French Ministry for Europe and Foreign Affairs.
The network of French Embassies in the participating countries acts as National Organizational Advisors, mobilizing academic networks and facilitating logistical, institutional, and communication support.
Local universities act as Local Operators, coordinating team definitions, participation venues, and logistical support.
The Regional Datathon is part of the France-Latin America Meeting on Open Science, an event co-organized by the French Ministry for Europe and Foreign Affairs, the French Ministry of Higher Education, Research, and Space, the French Embassy in Uruguay, the French Embassy in Argentina, the Uruguayan Secretariat for the Valorization of Science and Knowledge (SENCI), the Universidad de la República (Udelar) and the Uruguayan National Agency for Research and Innovation (ANII), and has the support of the European Union Delegations in Uruguay and Argentina.
The IV France-Latin America Meeting on Open Science aims to continue the dialogue initiated in Buenos Aires (2021), São Paulo (2022), and Paris (2023) among Latin American, European, and French experts on topics related to publications, data, software, infrastructure, research evaluation, artificial intelligence, and the fight against disinformation.